

Why AI workloads need specialized infrastructure
Training and serving AI models is resource-intensive. Large neural networks require parallel processing across multiple GPUs, high-speed interconnects, and massive data throughput. Storage systems must handle fast reads and writes for datasets used in training, tuning, and inference.
The operational profile is also different. AI workloads can stress power, cooling, network fabric, storage throughput, and scheduler design all at once. That makes monitoring, capacity planning, and AIOps for AI a core part of modern infrastructure management.
Key components of AI data centers
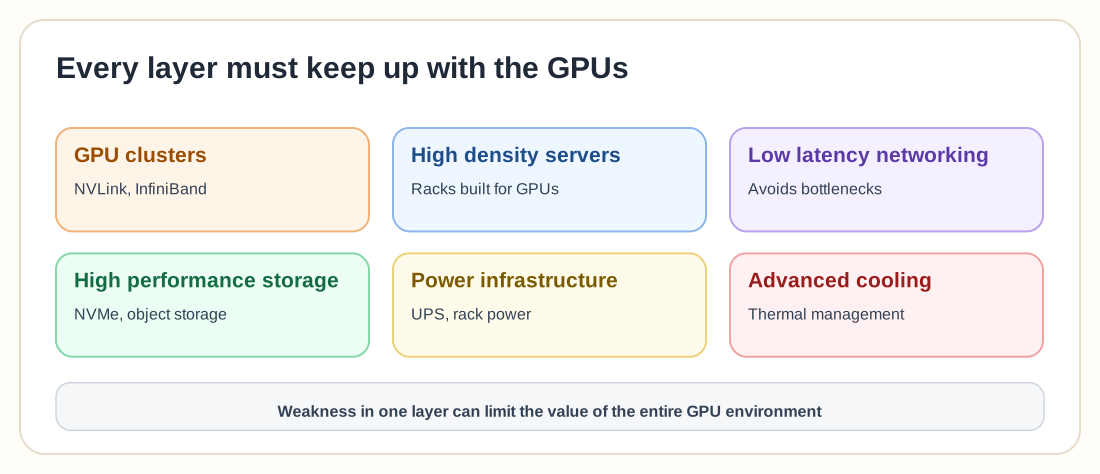
AI infrastructure depends on the relationship between compute, network, storage, power, and cooling. Weakness in one layer can limit the value of the entire GPU environment.
GPU Clusters
Modern AI relies heavily on GPUs for parallel processing. AI data centers often include multiple GPU nodes interconnected with high-speed networking such as NVLink or InfiniBand.
High-Density Servers
To optimize space and efficiency, AI data centers use high-density racks and servers designed for GPU hosting, power delivery, and thermal management.
Low-Latency Networking
High-bandwidth, low-latency networking helps GPUs and servers communicate efficiently. Network design determines whether training and inference hit bottlenecks.
High-Performance Storage
AI workloads need fast storage, including NVMe drives, parallel file systems, and object storage for large datasets used in training and inference.
Power Infrastructure
AI servers consume more power than traditional compute nodes, so UPS design, rack power delivery, and energy monitoring are essential for uptime.
Advanced Cooling
Dense GPU systems generate a lot of heat. Efficient cooling systems and thermal management strategies are required to maintain reliable operations.
Monitoring and AIOps in AI data centers
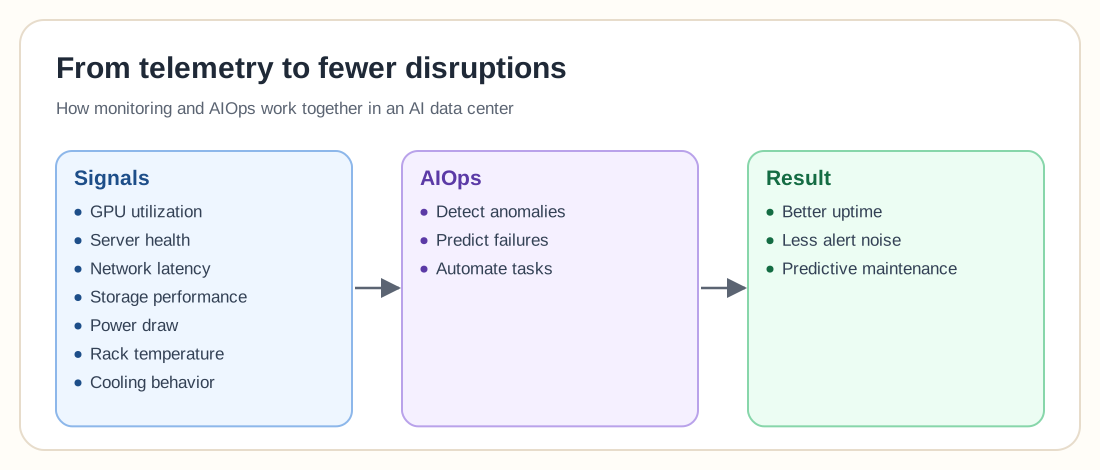
AI data centers need monitoring across GPU utilization, server health, network latency, storage performance, power draw, rack temperature, and cooling behavior. Teams need a unified view because performance issues often cross infrastructure boundaries.
AIOps platforms can analyze performance metrics, detect anomalies, predict potential failures, and automate operational tasks. For AI infrastructure, this can improve uptime, reduce alert noise, support predictive maintenance, and help operators respond before workload disruption becomes visible to the business.
Benefits of AI data centers
Specialized AI data centers organize facility design, platform engineering, and operations around high-performance AI workloads.
- High-performance infrastructure tailored for AI workloads
- Faster training and inference for machine learning models
- Improved power usage visibility and cooling efficiency
- Reduced downtime through predictive monitoring and automation
- Stronger foundation for hybrid cloud AI and enterprise AI platforms
Why AIOps matters for AI operations
AI infrastructure produces a large volume of telemetry from GPUs, servers, storage, network fabrics, and facility systems. Manual triage does not scale cleanly as clusters grow.
AIOps helps operations teams connect signals across systems, enrich incidents with infrastructure context, and make better decisions about capacity, placement, energy, and reliability.
Future trends in AI infrastructure
AI data centers are changing quickly as enterprises look for more efficient, scalable, and automated ways to support model training, inference, and hybrid cloud AI operations.
Hybrid Cloud AI
Enterprises will continue blending on-premises GPU infrastructure with cloud capacity for burst training, data gravity, governance, and cost control.
Multi-GPU Scaling
AI infrastructure planning will focus on faster interconnects, denser racks, and better scheduling across GPU clusters.
AI-Driven Energy Optimization
Power and cooling pressure will push teams toward smarter energy monitoring, thermal analytics, and automated efficiency improvements.
Intelligent Workload Scheduling
Operations teams will need better ways to place workloads based on GPU availability, thermal headroom, network paths, and business priority.
Explore more Data Center & AIOps resources
Continue with related guides for data center fundamentals, DCIM software, infrastructure roles, and AIOps-driven operations.
Data Center & AIOps Hub
Return to the parent section for DCIM, monitoring, AIOps, and operations planning.
What Is a Data Center?
Review the foundation behind enterprise infrastructure and data center operations.
Network Monitoring for Data Centers
Learn how latency, bandwidth, packet loss, and topology visibility affect AI operations.
DCIM Software Guide
Compare tools for asset management, power, cooling, analytics, and capacity planning.
AIOps Tools
Compare AI operations platforms for anomaly detection, predictive analytics, and automation.
Data Center Jobs and Roles
See how AI infrastructure and AIOps create career paths for infrastructure teams.
Connect AI infrastructure with smarter operations
Use the Data Center & AIOps hub to explore DCIM, monitoring, operations, and infrastructure management for AI-ready environments.